A Very Big Video Reasoning Suite
We bet on a future that video reasoning is the next fundamental intelligence paradigm, after language reasoning, where spatiotemporal embodied world experiences could be more naturally captured.
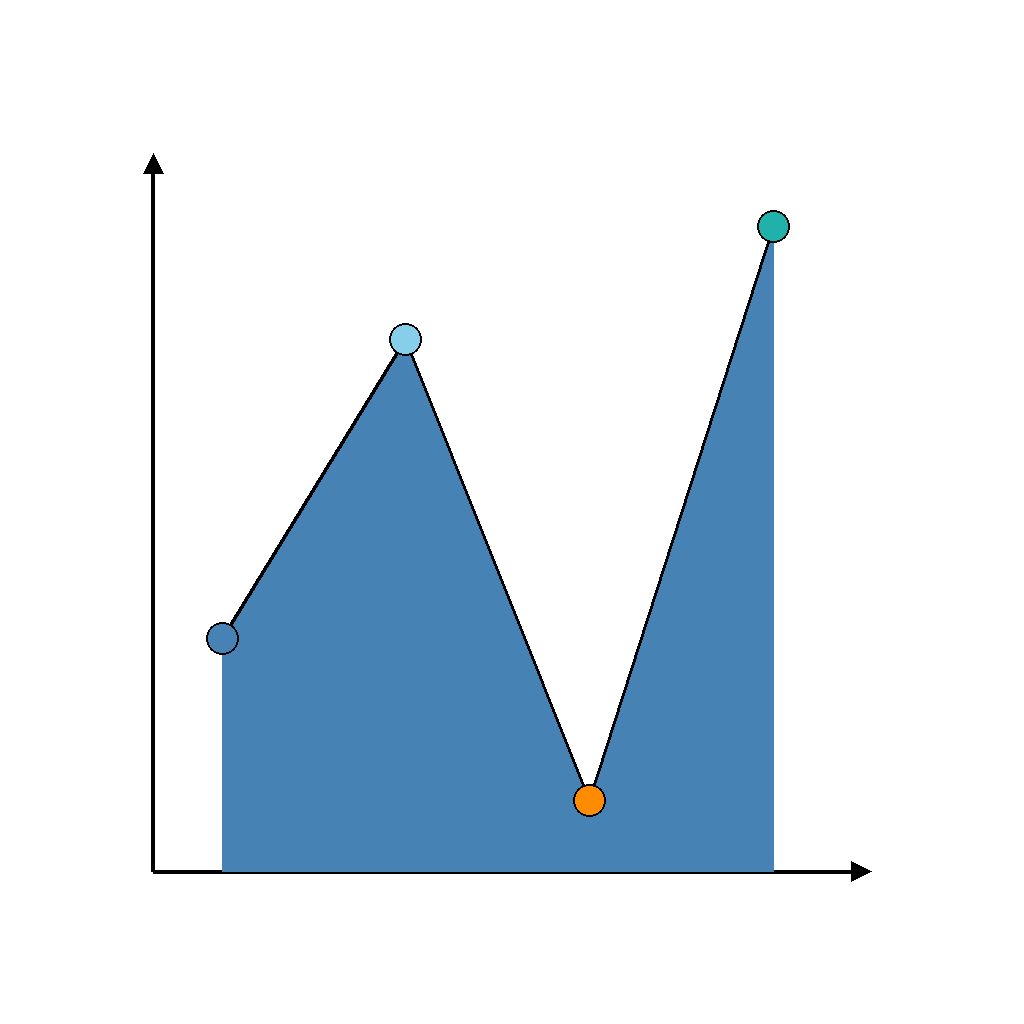
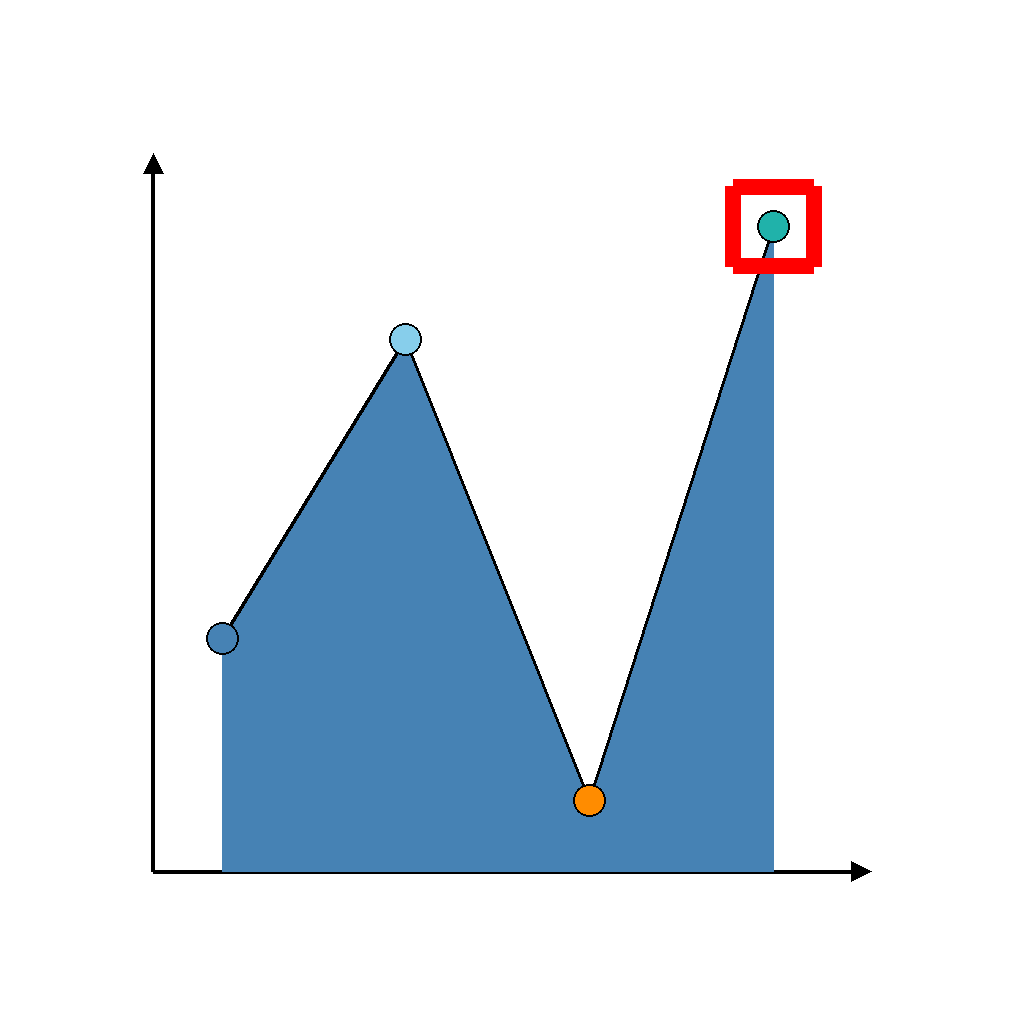
chart_extreme_without_data
GitHub
Prompt
The scene shows a bar chart. Find the maximum value bar and draw a red rectangular border around the corresponding bar to highlight it.
First Frame
Last Frame
Video
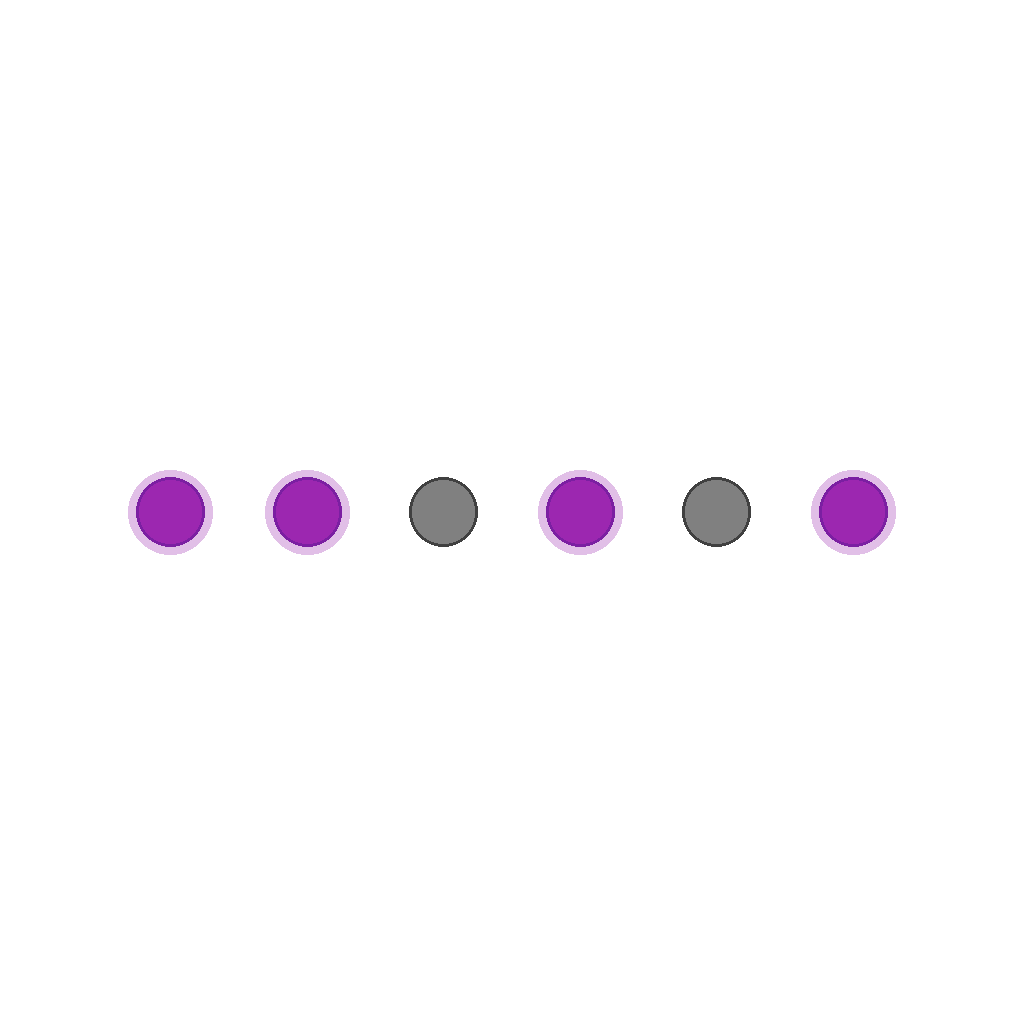
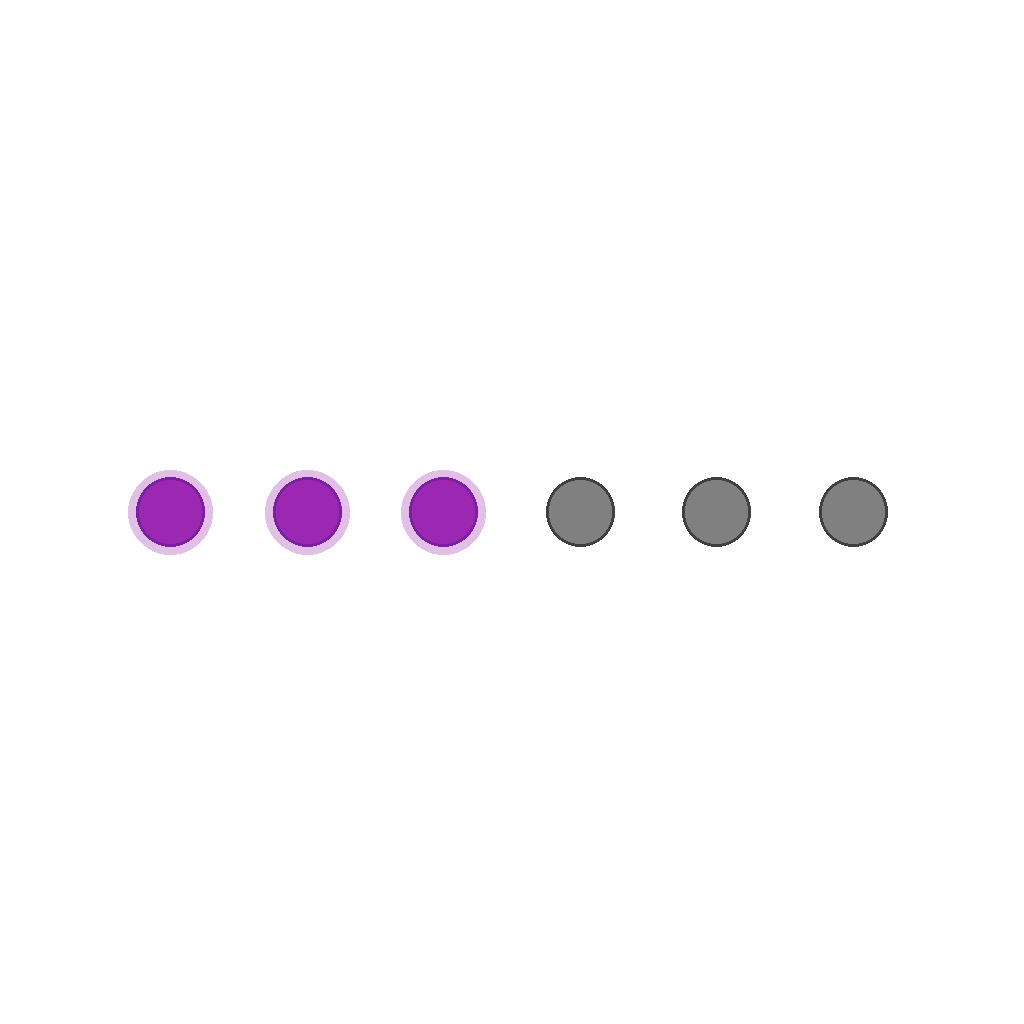
light_sequence
GitHub
Prompt
The scene shows 6 circular lights in a horizontal row on a white background. Lights on are orange with glow; lights off are gray. Initially, some lights are on and some are off.
Your task: Modify the light states so that all lights at even positions (counting from left to right: 1st is odd, 2nd is even, 3rd is odd, and so on) are on (orange with glow), and all lights at odd positions are off (gray). Turn lights on/off as needed. Lights change from gray to orange (with glow) when turned on, and from orange to gray (glow disappears) when turned off. Lights stay in fixed positions; only their states change.
First Frame
Last Frame
Video
LEGO_construction_assembly
GitHub
Prompt
This is LEGO assembly step 4. The scene shows a partial model on the right and a 1x1 green brick on the left in a callout box. Take the green brick and attach it to the model at the position indicated by the red arrow. Move the brick smoothly from the callout to its destination, align it correctly, and snap it into place.
First Frame
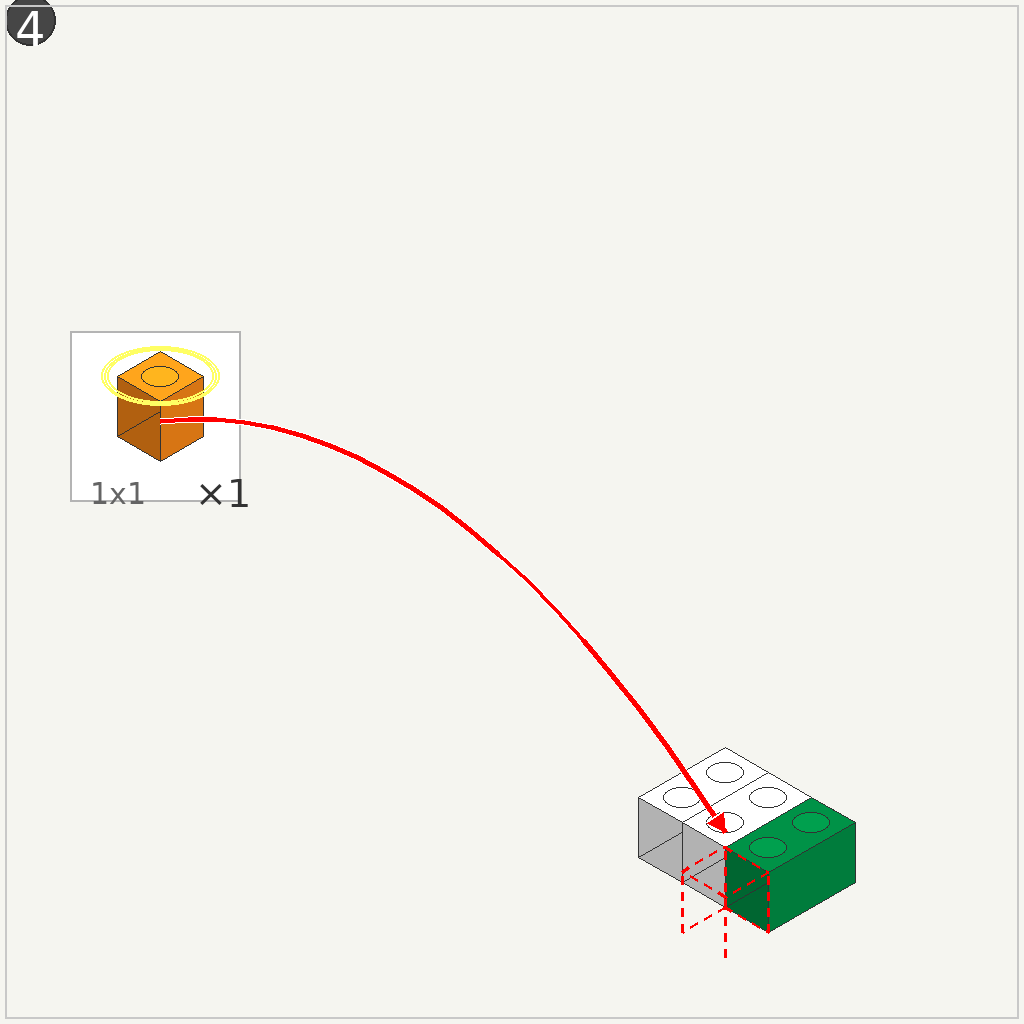
Last Frame
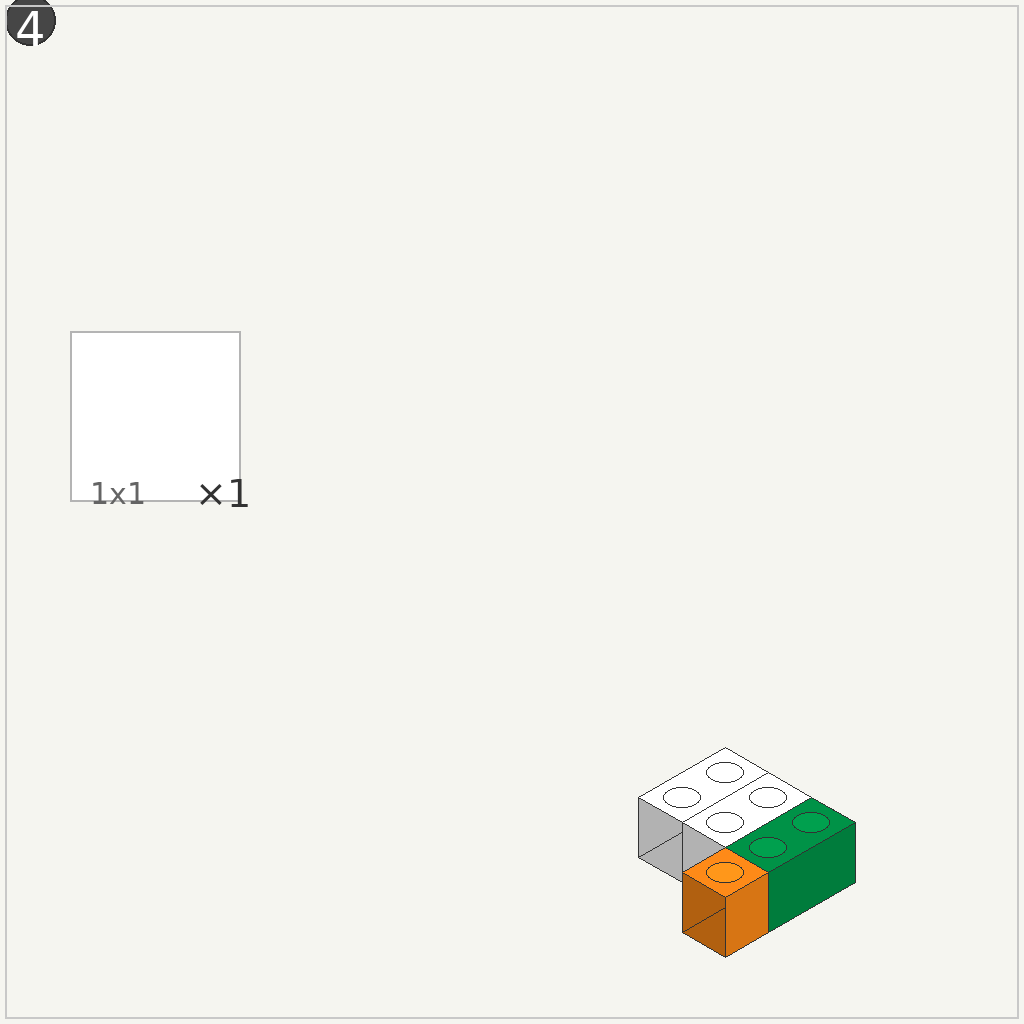
Video
object_packing
GitHub
Prompt
The scene shows objects on the left side and a container on the right side. Place the objects into the container one by one in the color order: orange - brown. Each object must be placed individually in the exact order specified, and all objects must end up inside the container.
First Frame
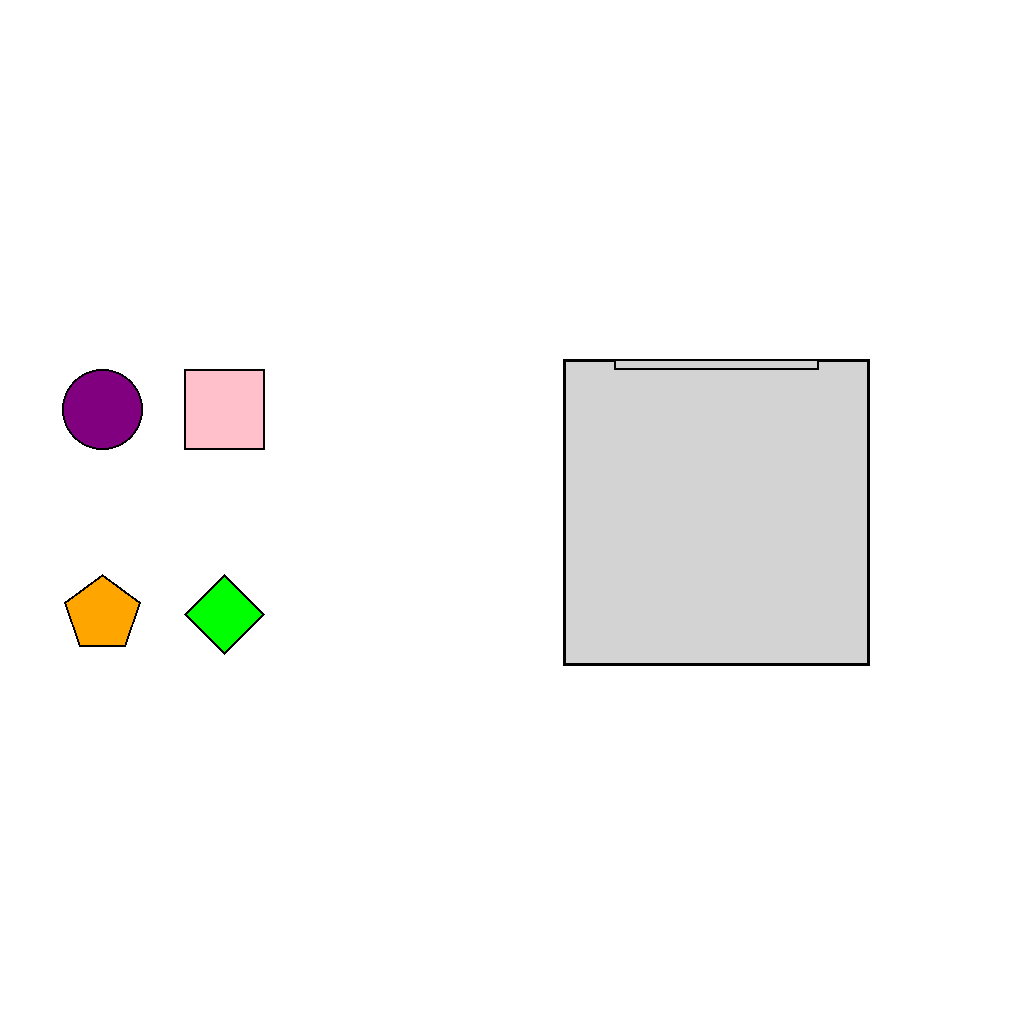
Last Frame
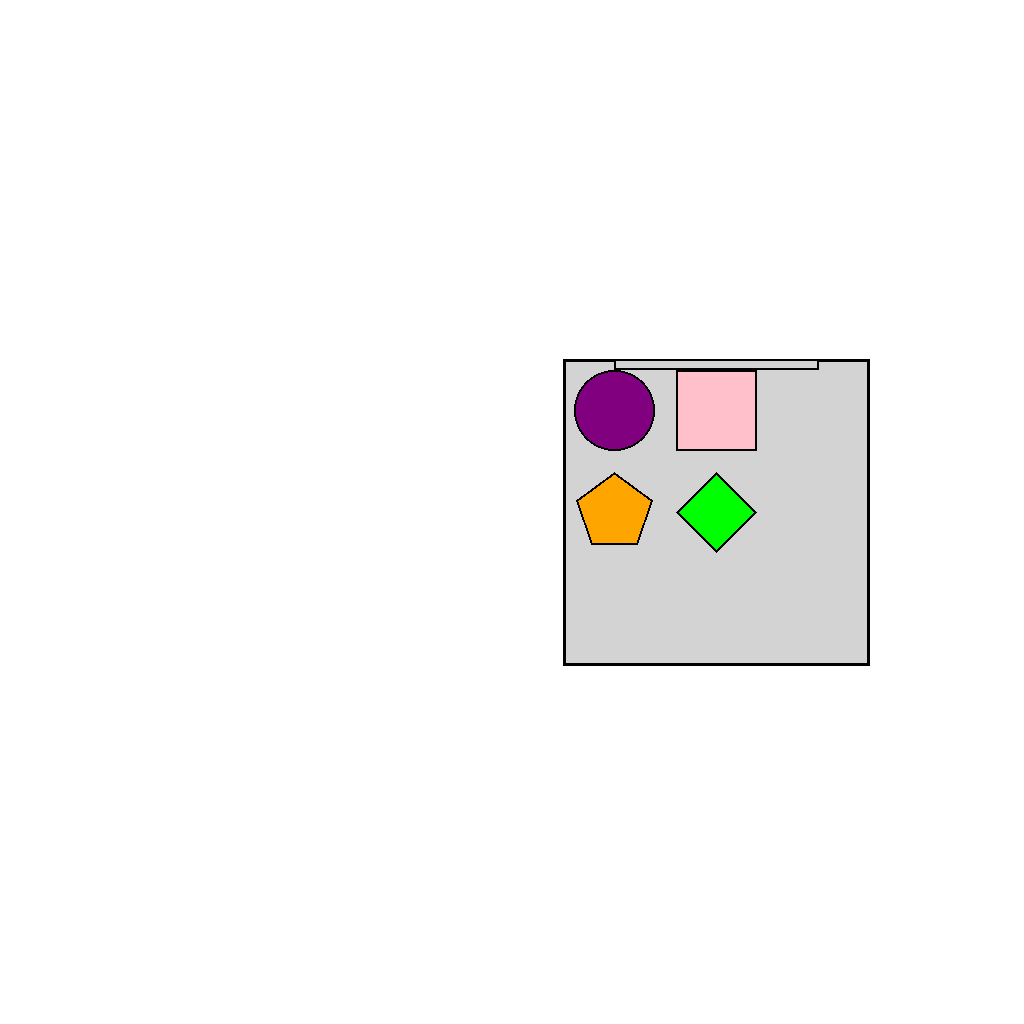
Video
animal_size_sorting
GitHub
Prompt
Animal faces of different sizes are scattered randomly on the canvas. Sort them by size from smallest to largest and align them horizontally at the bottom baseline.
First Frame
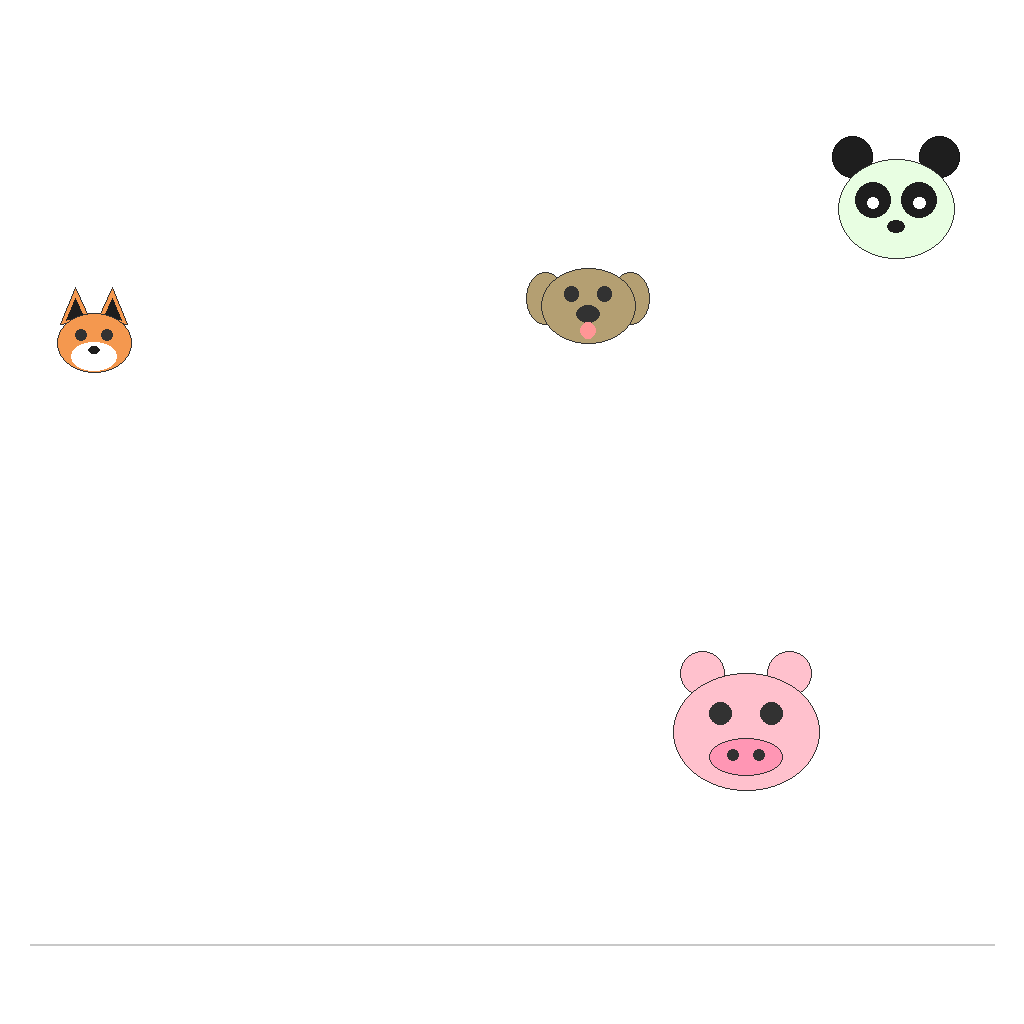
Last Frame
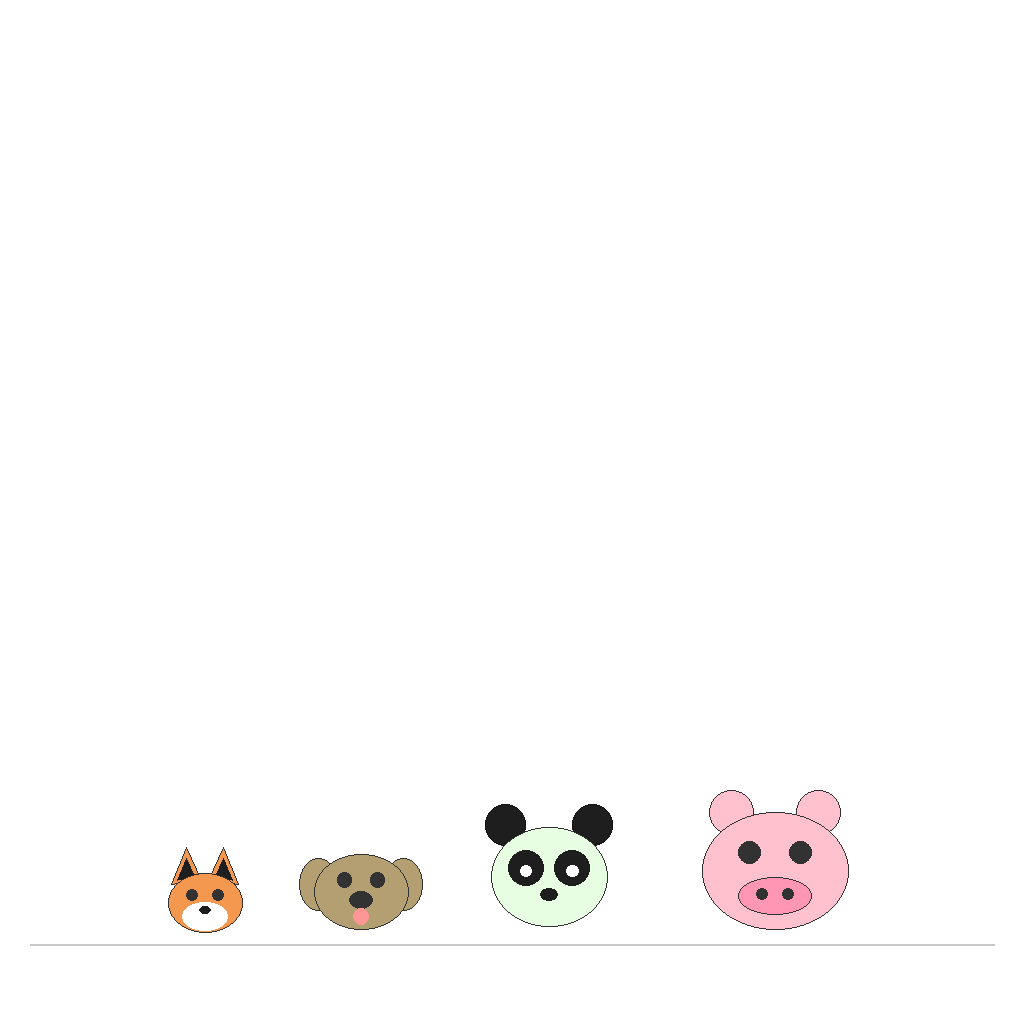
Video
Dot to Dot - Samples
00
01
02
03
04
Prompt
Loading...
Ground Truth
First
Final
Model Outputs
1/
VBVR-Wan2.2
VBVR-Wan2.2
CogVideoX 1.5
Kling 2.6
LTX-2
Runway Gen-4
Sora 2
Veo 3
Wan 2.2 I2V
Hunyuan I2V
Seedance 2.0
Leaderboard
Modality
Split
Type
Category
Citation
If you find VBVR useful in your research, please cite our paper.
@inproceedings{vbvr2026,
  title     = {A Very Big Video Reasoning Suite},
  author    = {Wang, Maijunxian and Wang, Ruisi and Lin, Juyi and Ji, Ran and Wiedemer, Thadd{\"a}us and
             Gao, Qingying and Luo, Dezhi and Qian, Yaoyao and Huang, Lianyu and Hong, Zelong and
             Ge, Jiahui and Ma, Qianli and He, Hang and Zhou, Yifan and Guo, Lingzi and Mei, Lantao and
             Li, Jiachen and Xing, Hanwen and Zhao, Tianqi and Yu, Fengyuan and Xiao, Weihang and
             Jiao, Yizheng and Hou, Jianheng and Zhang, Danyang and Xu, Pengcheng and Zhong, Boyang and
             Zhao, Zehong and Fang, Gaoyun and Kitaoka, John and Xu, Yile and Xu, Hua and
             Blacutt, Kenton and Nguyen, Tin and Song, Siyuan and Sun, Haoran and Wen, Shaoyue and
             He, Linyang and Wang, Runming and Wang, Yanzhi and Yang, Mengyue and Ma, Ziqiao and
             Milli{\`e}re, Rapha{\"e}l and Shi, Freda and Vasconcelos, Nuno and Khashabi, Daniel and
             Yuille, Alan and Du, Yilun and Liu, Ziming and Lin, Dahua and Liu, Ziwei and Kumar, Vikash and
             Li, Yijiang and Yang, Lei and Cai, Zhongang and Deng, Hokin},
  booktitle = {Proceedings of the 43rd International Conference on Machine Learning},
  year      = {2026},
  url       = {https://arxiv.org/abs/2602.20159}
}